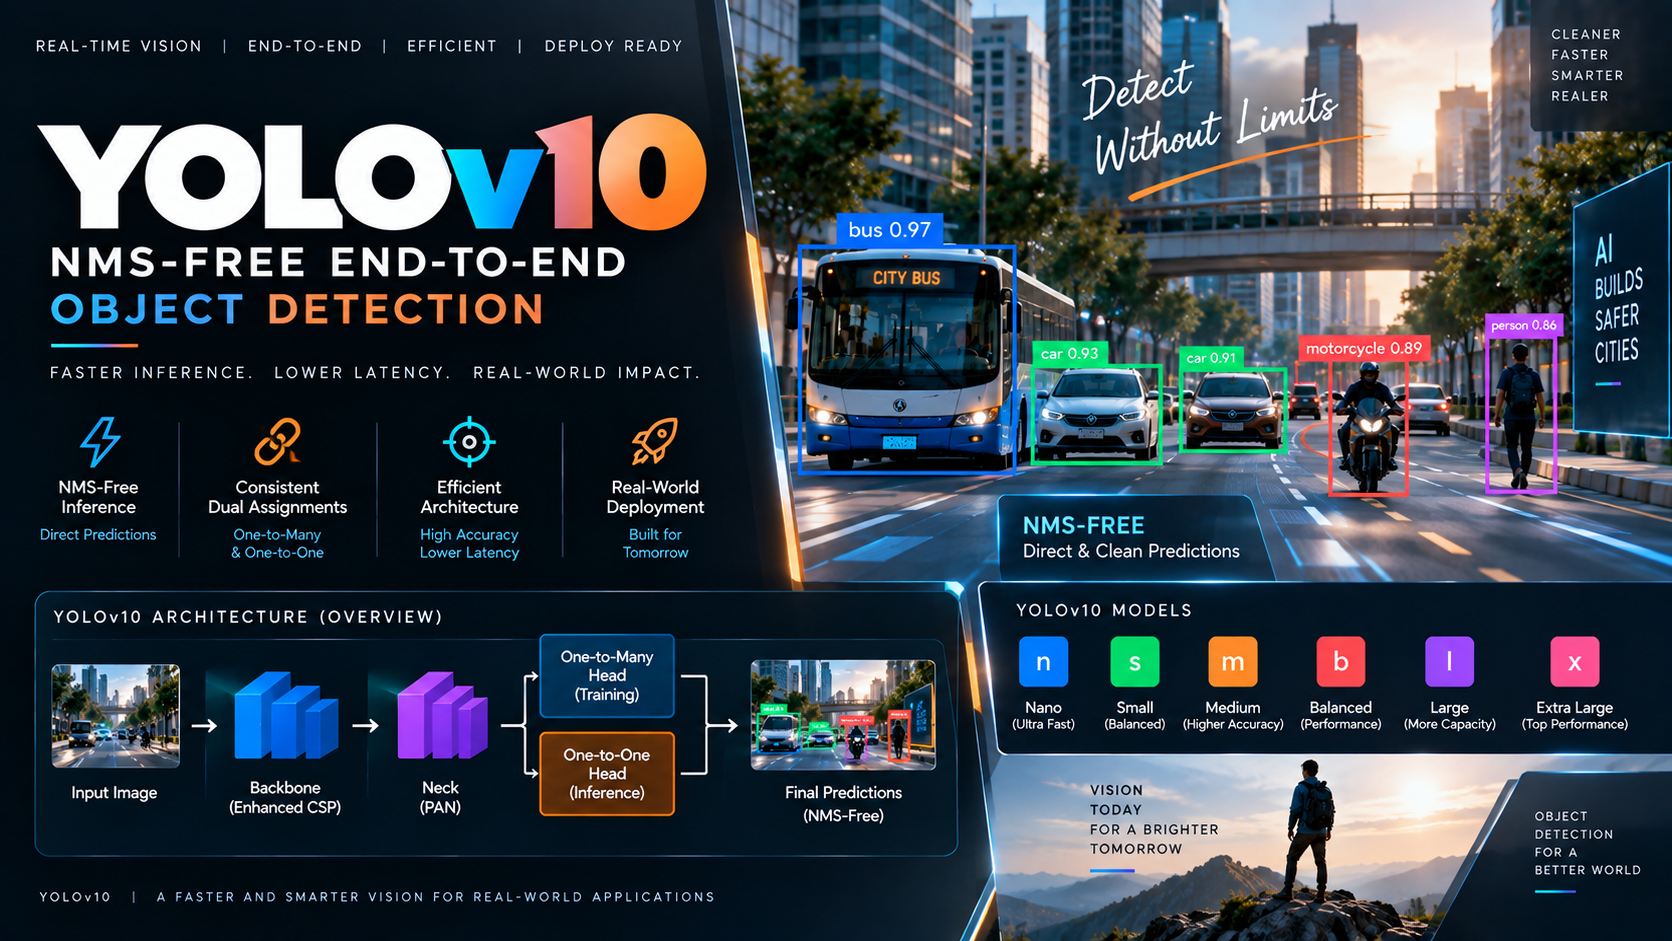
YOLOv10: NMS-Free End-to-End Object Detection
Introduction
YOLOv10 was introduced in May 2024 by researchers from Tsinghua University. The model focused on improving the efficiency of real-time object detection by addressing two major issues: unnecessary computational redundancy inside the network and the latency introduced by Non-Maximum Suppression (NMS) during post-processing.
The key idea behind YOLOv10 is to move toward end-to-end object detection, allowing the model to produce final predictions without requiring a separate NMS step.
What is YOLOv10?
YOLOv10 is a real-time object detection model designed around an NMS-free inference approach.
Traditional YOLO detectors can produce multiple overlapping predictions for the same object, after which NMS is used to remove redundant boxes. YOLOv10 introduces consistent dual assignments, allowing the model to learn both one-to-many and one-to-one prediction strategies during training. The one-to-one head can then produce a single prediction per object during NMS-free inference.
Why Was YOLOv10 Introduced?
Previous object detectors often required post-processing after neural-network inference. Although NMS is effective, it adds additional computation and can make deployment more complicated.
YOLOv10 addresses this by combining:
- NMS-free end-to-end detection
- Consistent dual assignments
- Efficient architectural design
- Lightweight classification components
- Improved feature extraction
- Optimized downsampling
- Large-kernel convolution
- Partial Self-Attention
These changes were designed to improve the speed-accuracy balance of real-time detection systems.
YOLOv10 Architecture
Enhanced CSP-Based Backbone
The backbone extracts visual features from input images while reducing unnecessary computation and improving gradient flow.
PAN-Based Neck
The neck combines information from different feature levels, allowing the detector to recognize objects of different sizes.
One-to-Many Head
During training, the one-to-many head generates multiple predictions for an object. This provides richer supervision and helps the model learn effectively.
One-to-One Head
The one-to-one head is designed to generate a single prediction for each object during inference. This enables the NMS-free detection approach.
Consistent Dual Assignments
One of YOLOv10's most important innovations is consistent dual assignment.
During training, YOLOv10 uses both:
One-to-Many Assignment → provides rich training supervision.
One-to-One Assignment → prepares the model for end-to-end prediction without NMS.
The training strategy aligns these two prediction processes so that the final one-to-one predictions can be used directly during NMS-free inference.
Key Features of YOLOv10
- NMS-free end-to-end detection
- Consistent dual assignments
- One-to-many and one-to-one detection heads
- Holistic efficiency-accuracy optimization
- Lightweight classification head
- Spatial-channel decoupled downsampling
- Rank-guided block design
- Large-kernel convolution
- Partial Self-Attention
- Multiple model sizes
YOLOv10 Model Variants
YOLOv10 is available in several configurations:
- YOLOv10n – Nano
- YOLOv10s – Small
- YOLOv10m – Medium
- YOLOv10b – Balanced
- YOLOv10l – Large
- YOLOv10x – Extra Large
The different variants allow developers to select a model according to their available hardware and desired speed-accuracy balance.
Advantages of YOLOv10
YOLOv10 provides several practical advantages:
- Reduced post-processing overhead
- Lower inference latency
- End-to-end detection design
- Efficient model architecture
- Multiple model sizes
- Suitable for real-time applications
- Easier deployment on hardware where NMS can be difficult to optimize
The original research reported, for example, that YOLOv10-S was faster than RT-DETR-R18 at similar COCO AP, while YOLOv10-B achieved lower latency and fewer parameters than YOLOv9-C at comparable performance under the reported evaluation settings.
Limitations
YOLOv10 is still primarily focused on object detection rather than the broader collection of tasks supported by some other YOLO versions. Ultralytics currently lists YOLOv10 as a detection model.
Larger variants also require more computational resources. As with other object detectors, real-world performance depends on dataset quality, image resolution, object size, hardware, and environmental conditions.
YOLOv9 vs YOLOv10
| Feature | YOLOv9 | YOLOv10 |
|---|---|---|
| Main focus | Information preservation | End-to-end efficiency |
| Major innovation | PGI | Consistent dual assignments |
| Architecture | GELAN | Efficiency-optimized YOLO architecture |
| NMS | Traditional detection pipeline | NMS-free inference approach |
| Detection heads | Standard detection design | One-to-many + one-to-one |
| Model variants | T/S/M/C/E | N/S/M/B/L/X |
| Primary task | Detection and segmentation variants | Object detection |
YOLOv9 concentrated heavily on information flow and gradient preservation, while YOLOv10 focused on reducing inference and post-processing overhead through an end-to-end detection strategy.
Applications
YOLOv10 can be used for:
- Vehicle detection
- Traffic monitoring
- Surveillance
- Industrial inspection
- Robotics
- Autonomous systems
- Smart-city applications
- Retail analytics
- Real-time video analysis
- Edge AI applications
Its low-latency design is particularly relevant to applications where fast inference and efficient deployment are important.
Conclusion
YOLOv10 represents an important step toward end-to-end real-time object detection. Its combination of consistent dual assignments, one-to-one prediction, and efficiency-focused architectural improvements reduces the dependency on traditional NMS post-processing.
By focusing not only on detection accuracy but also on the complete inference pipeline, YOLOv10 demonstrates how modern object detectors can become faster and more deployment-friendly.
Comments (0)
No comments yet. Be the first to share your thoughts!
Join the Conversation
Please log in to your Teltam account to post a comment on this article.
Log In to Comment