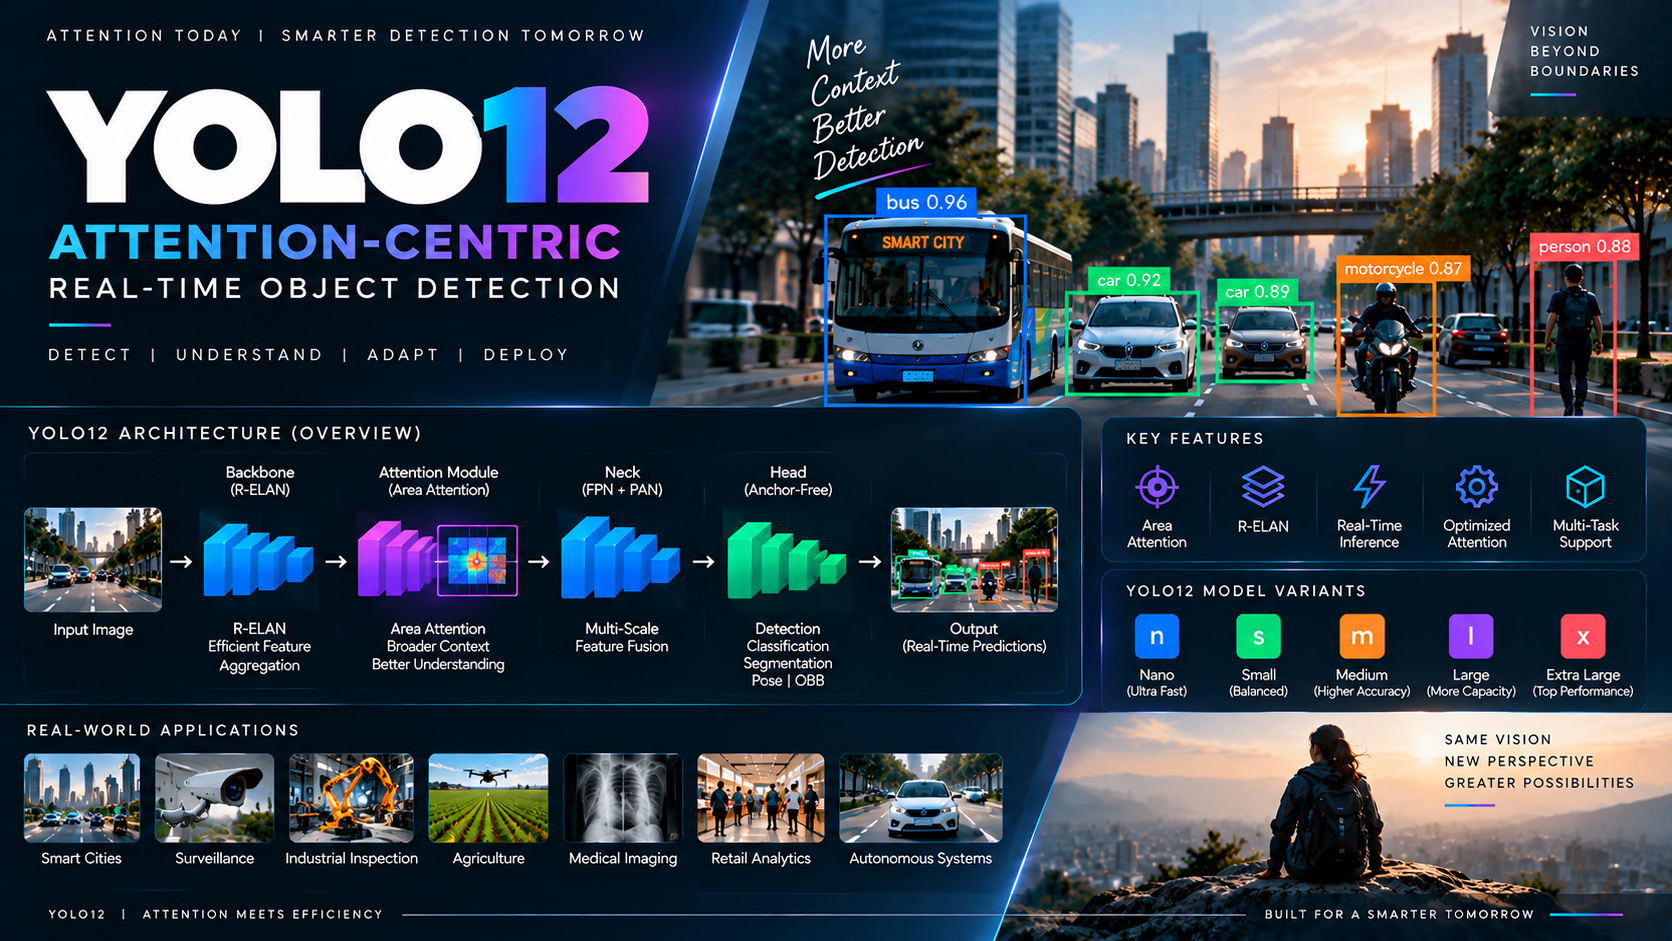
YOLO12: Attention-Centric Real-Time Object Detection
Introduction
YOLO12 is an attention-centric real-time object detection model introduced in February 2025 by researchers from the University at Buffalo and the University of Chinese Academy of Sciences. It explores how attention mechanisms can improve visual feature processing while maintaining the speed expected from YOLO-based detectors.
Unlike earlier YOLO architectures that primarily relied on convolutional feature extraction, YOLO12 integrates attention-based components to capture broader contextual information. Its major architectural ideas include Area Attention, R-ELAN, and optimized attention mechanisms.
What is YOLO12?
YOLO12 is a computer vision model designed to balance detection accuracy, computational efficiency, and inference speed. It applies attention mechanisms to help the model identify important relationships within image features.
The model supports several computer vision tasks through its architecture, including object detection, instance segmentation, classification, pose estimation, and oriented bounding-box detection. However, the availability of pretrained weights differs between tasks and implementations.
Why Was YOLO12 Introduced?
Traditional convolutional networks are efficient at processing local image patterns, but attention mechanisms can help capture relationships across larger regions of an image.
YOLO12 was developed to explore the advantages of attention-based feature processing without losing the real-time characteristics of the YOLO family.
Its main objectives include:
-
Improving feature representation
-
Capturing broader contextual information
-
Maintaining efficient inference
-
Improving the speed-accuracy balance
-
Supporting multiple computer vision tasks
YOLO12 Architecture
1. Area Attention
Area Attention is one of the main innovations in YOLO12. Instead of applying standard self-attention across an entire feature map, the feature map is divided into regions.
This approach helps process larger receptive fields while controlling computational complexity. It is designed to capture useful contextual relationships more efficiently than conventional global attention.
2. R-ELAN
Residual Efficient Layer Aggregation Network, or R-ELAN, improves feature aggregation and optimization in attention-centric architectures.
It uses residual connections and redesigned feature integration to help the network learn effectively, especially in larger model configurations.
3. Optimized Attention
YOLO12 includes several attention optimizations, such as efficient attention processing, modified MLP ratios, and the use of convolutional operations where they are computationally beneficial.
FlashAttention can also be used in supported environments, although it is not required for the standard YOLO12 implementation.
4. Position Perceiver
A 7×7 separable convolution is used as a position-perceiving component in the attention design. It helps incorporate spatial information without relying entirely on conventional positional encoding.
Key Features of YOLO12
-
Attention-centric architecture
-
Area Attention mechanism
-
R-ELAN feature aggregation
-
Optimized attention processing
-
Improved contextual feature learning
-
Multiple model sizes
-
Support for several computer vision tasks
-
Flexible edge and cloud deployment options
YOLO12 Model Sizes
YOLO12 is available in different model configurations:
-
YOLO12n – Nano
-
YOLO12s – Small
-
YOLO12m – Medium
-
YOLO12l – Large
-
YOLO12x – Extra Large
Smaller models can be considered for resource-constrained applications, while larger models provide increased model capacity for more demanding detection tasks.
Advantages of YOLO12
YOLO12 offers several potential advantages:
-
Attention-based feature extraction
-
Improved contextual understanding
-
Multiple model configurations
-
Support for real-time object detection
-
Flexible architecture for research and experimentation
-
Support for various computer vision tasks
-
Potential use across edge and cloud environments
The original YOLO12 research reports accuracy improvements over several real-time detectors at comparable speed settings. Actual performance depends on the model variant, hardware, inference configuration, and evaluation methodology.
Limitations
Attention-based components can increase memory requirements and may introduce additional training complexity. YOLO12 may also have slower CPU throughput or higher memory usage than some earlier YOLO models, depending on the implementation.
Ultralytics describes its YOLO12 implementation as a community-oriented model and recommends considering YOLO11 or YOLO26 for some production scenarios where training stability and predictable deployment performance are important.
The availability of pretrained weights also differs across tasks. Official pretrained weights are available for detection in the Ultralytics implementation, while other task architectures may require training from their configuration files.
YOLO11 vs YOLO12
|
Feature |
YOLO11 |
YOLO12 |
|---|---|---|
|
Main Focus |
Efficient multi-task vision |
Attention-centric detection |
|
Architecture |
C3k2 + C2PSA |
Area Attention + R-ELAN |
|
Major Innovation |
Efficient feature extraction |
Attention-based feature learning |
|
Supported Tasks |
Detection, segmentation, classification, pose, OBB |
Detection and other supported vision tasks |
|
Primary Use |
Production and real-time applications |
Research and attention-based vision experiments |
YOLO11 and YOLO12 both target efficient computer vision, but YOLO12 explores a stronger role for attention mechanisms in the YOLO architecture.
Applications
YOLO12 can be explored for:
-
Vehicle detection
-
Traffic monitoring
-
Industrial inspection
-
Robotics
-
Surveillance
-
Autonomous systems
-
Retail analytics
-
Medical image analysis
-
Smart-city applications
-
Real-time video analysis
Its attention-based architecture may be useful in scenarios where contextual information and relationships between visual features are important.
Conclusion
YOLO12 introduces an attention-centric direction for the YOLO family. Its combination of Area Attention, R-ELAN, and optimized attention processing aims to improve feature representation while maintaining competitive real-time performance.
Although attention-based components introduce potential challenges involving memory usage and training stability, YOLO12 provides an important research direction for combining the contextual capabilities of attention mechanisms with the efficiency of real-time object detection.
Comments (0)
No comments yet. Be the first to share your thoughts!
Join the Conversation
Please log in to your Teltam account to post a comment on this article.
Log In to Comment