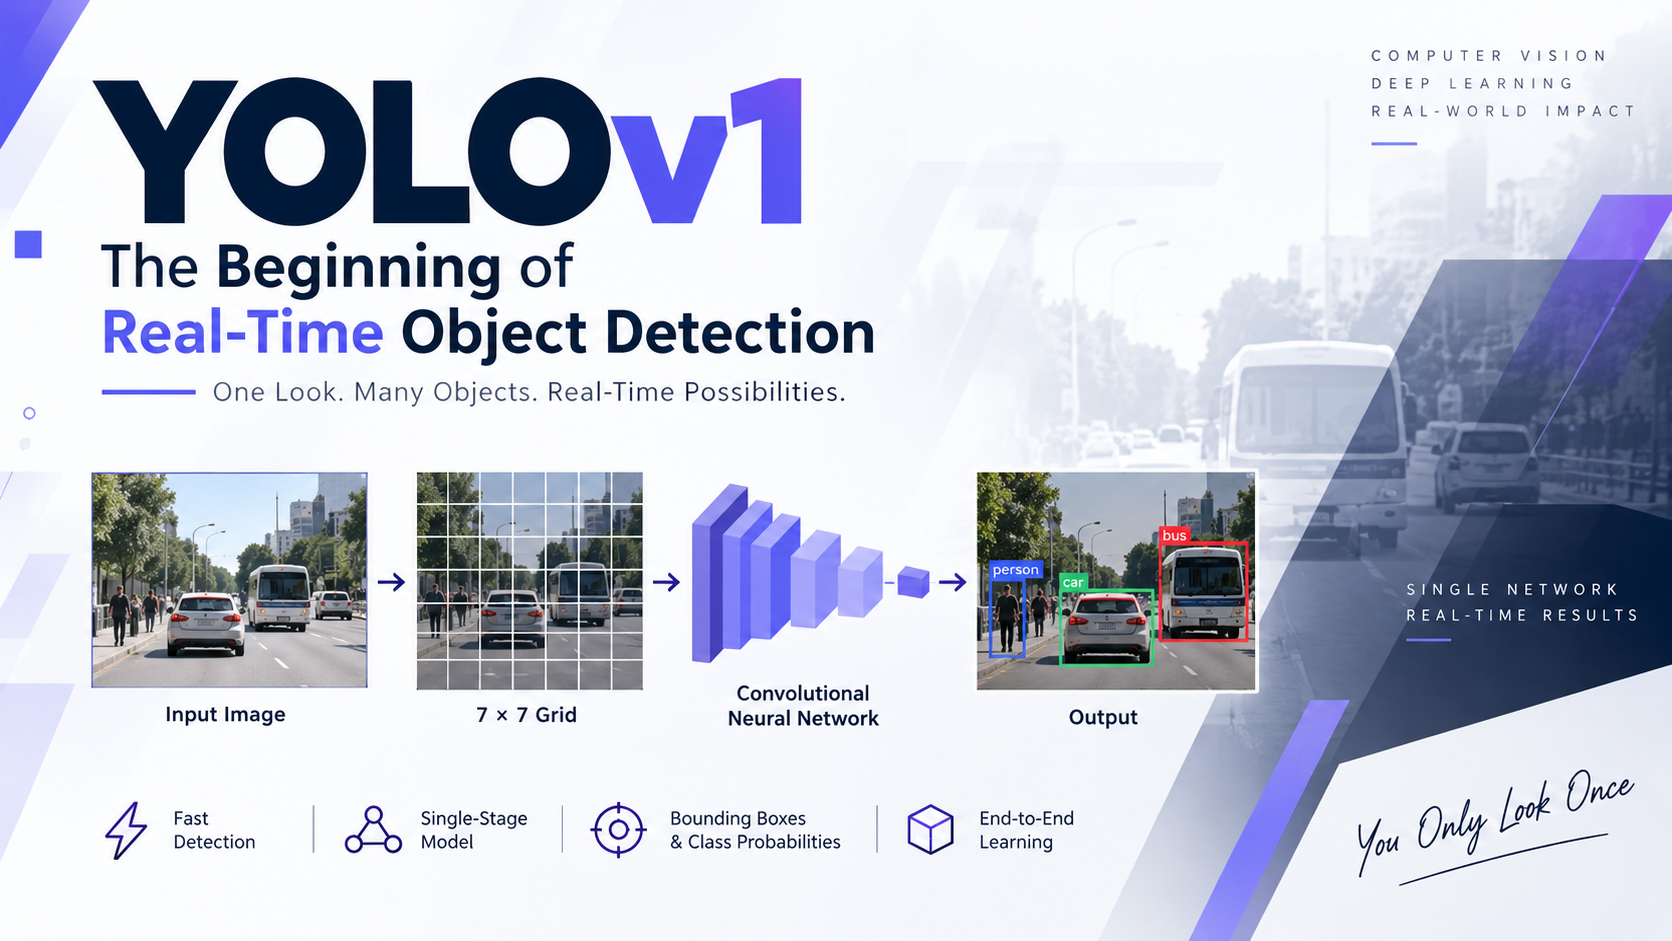
YOLOv1: The Beginning of Real-Time Object Detection
Introduction
Object detection is an important task in computer vision that involves identifying objects in an image and locating them using bounding boxes. Before YOLO, many object detection approaches used multiple stages, such as generating candidate regions and then classifying those regions. Although these methods could achieve good accuracy, they often required significant computational resources and were not always suitable for real-time applications.
YOLO (You Only Look Once) introduced a new approach to object detection by treating it as a single regression problem. Instead of examining different regions of an image separately, YOLO processes the entire image through a single neural network and directly predicts object locations and class probabilities.
YOLOv1 was introduced in the research paper “You Only Look Once: Unified, Real-Time Object Detection” by Joseph Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi in 2015. It became an important milestone in the development of fast and practical object detection systems.
What is YOLOv1?
YOLOv1 (You Only Look Once version 1) is a deep-learning-based object detection algorithm designed to perform object detection using a single neural network.
The model simultaneously predicts:
- The location of objects
- The size of objects
- The confidence of predictions
- The class of each detected object
The basic workflow can be represented as:
Input Image → Convolutional Neural Network → Bounding Boxes + Confidence Scores + Class Probabilities
This unified approach significantly reduced the processing time compared with many traditional object detection methods.
Why Was YOLOv1 Introduced?
Traditional object detection systems often used techniques such as sliding windows or region proposals. These methods processed multiple portions of an image, which increased computational requirements.
YOLOv1 changed this approach by looking at the entire image at once.
The model learned object detection directly from the complete image and produced the required predictions in a single forward pass.
This made YOLO particularly suitable for applications where detection speed was important, including:
- Video surveillance
- Traffic monitoring
- Robotics
- Autonomous systems
- Real-time video analysis
- Industrial inspection
How Does YOLOv1 Work?
YOLOv1 divides an input image into an S × S grid.
For the original YOLOv1 model, the image is divided into a:
7 × 7 grid
Each grid cell is responsible for detecting an object if the center of that object falls inside the particular grid cell.
For each grid cell, YOLOv1 predicts:
- 2 bounding boxes
- 2 confidence scores
- 20 class probabilities when trained on the PASCAL VOC dataset
The complete image is therefore processed by the neural network in one pass.
Bounding Box Prediction
Each bounding box prediction contains five values:
x, y, w, h, confidence
Where:
- x represents the horizontal position of the bounding-box center.
- y represents the vertical position of the bounding-box center.
- w represents the width of the bounding box.
- h represents the height of the bounding box.
- confidence represents the model's confidence that the bounding box contains an object and reflects the predicted overlap with the ground-truth box.
Along with the bounding boxes, the model predicts class probabilities for the detected objects.
YOLOv1 Architecture
YOLOv1 uses a convolutional neural network architecture inspired by GoogLeNet.
The original YOLO network contains:
- 24 convolutional layers
- 2 fully connected layers
The convolutional layers are responsible for extracting visual features from the input image. The fully connected layers use these learned features to generate the final object detection predictions.
The architecture also uses 1 × 1 convolutional layers followed by 3 × 3 convolutional layers in several parts of the network.
The final layer produces the detection predictions for all grid cells.
YOLOv1 Architecture Flow
Input Image
↓
Convolutional Layers
↓
Feature Extraction
↓
Fully Connected Layers
↓
7 × 7 × 30 Prediction Tensor
↓
Bounding Boxes + Confidence Scores + Class Probabilities
YOLOv1 Output
When YOLOv1 is trained using the PASCAL VOC dataset, it uses:
- S = 7 grid cells in each dimension
- B = 2 bounding boxes per grid cell
- C = 20 object classes
Each bounding box contains 5 values:
x, y, w, h, confidence
Therefore, each grid cell produces:
2 × 5 + 20 = 30 values
The final output is:
7 × 7 × 30
This gives a total of:
1,470 predicted values
These predictions are then processed to obtain the final object detections.
Training YOLOv1
YOLOv1 is trained using images containing objects together with their corresponding bounding-box annotations.
The model uses a multi-part loss function that combines several objectives:
- Bounding-box localization
- Bounding-box dimensions
- Object confidence
- No-object confidence
- Object classification
The localization component helps the model learn accurate object positions and dimensions.
The confidence component helps the model distinguish between bounding boxes containing objects and those that do not.
The classification component helps the model determine which object category is present.
YOLOv1 also gives greater importance to localization errors and reduces the influence of confidence errors from cells that do not contain objects.
Non-Maximum Suppression
A single object may sometimes result in multiple bounding-box predictions. To remove redundant detections, YOLOv1 uses Non-Maximum Suppression (NMS).
The general process is:
- Generate bounding-box predictions.
- Calculate confidence scores.
- Select the prediction with the highest confidence.
- Compare it with other overlapping predictions.
- Remove highly overlapping redundant boxes.
- Continue until the final detections remain.
This helps produce a cleaner object detection result.
Key Features of YOLOv1
1. Single-Stage Object Detection
YOLOv1 performs detection using a single neural network rather than a separate region-proposal stage.
2. Real-Time Performance
One of the major achievements of YOLOv1 was its high detection speed. The original paper reported approximately 45 frames per second (FPS) for the standard YOLO model and up to 155 FPS for a smaller version called Fast YOLO.
3. Global Image Understanding
YOLOv1 processes the entire image during prediction. This allows the network to use global contextual information when making detection decisions.
4. Unified Detection Pipeline
Object localization and classification are handled within the same neural network.
5. End-to-End Training
The complete detection system can be trained directly from input images to object detection predictions.
Advantages of YOLOv1
YOLOv1 introduced several important advantages:
- Fast object detection
- Single neural network for detection
- End-to-end training
- Real-time processing capability
- Global image context
- Simple detection pipeline
- Suitable for video-based applications
Its speed made it particularly useful for applications that required rapid object detection rather than processing images only for offline analysis.
Limitations of YOLOv1
Despite its significant advantages, YOLOv1 also had several limitations.
1. Difficulty Detecting Small Objects
Because the image is divided into a fixed grid, YOLOv1 can have difficulty detecting small objects, especially when multiple small objects are located close together.
2. Limited Predictions Per Grid Cell
Each grid cell predicts only a fixed number of bounding boxes. This limits the number of objects that can be detected when several object centers fall within the same cell.
3. Localization Errors
YOLOv1 can produce less accurate bounding-box localization compared with some other detection approaches.
4. Difficulty With Groups of Objects
When multiple objects appear close to one another, particularly when their centers fall within the same grid cell, YOLOv1 may struggle to separate them correctly.
5. Coarse Spatial Representation
The 7 × 7 grid provides a relatively coarse representation of object locations, which can affect the detection of small or closely positioned objects.
YOLOv1 Performance
YOLOv1 was designed with a strong focus on speed while maintaining useful detection accuracy.
The original YOLO model achieved approximately 45 FPS, while Fast YOLO achieved approximately 155 FPS under the evaluation conditions described in the original research paper.
This demonstrated that deep-learning-based object detection could be performed at real-time speeds and helped establish a foundation for subsequent YOLO versions.
Applications of YOLOv1
The concept introduced by YOLOv1 can be applied to many computer vision applications, including:
- Vehicle detection
- Pedestrian detection
- Traffic monitoring
- Video surveillance
- Robotics
- Autonomous systems
- Industrial object detection
- Security monitoring
- Real-time video analytics
Although newer YOLO versions provide substantial improvements, the core idea introduced by YOLOv1 continues to influence modern real-time object detection systems.
YOLOv1 vs Traditional Object Detection
The main difference between YOLOv1 and many earlier approaches is the way object detection is formulated.
| Aspect | Traditional Multi-Stage Methods | YOLOv1 |
|---|---|---|
| Detection approach | Multiple stages | Single-stage |
| Image processing | Multiple regions/proposals | Entire image |
| Network | May involve separate components | Single neural network |
| Training | Multiple objectives/stages | End-to-end |
| Speed | Generally slower | Designed for real-time detection |
| Global context | More limited | Uses the entire image |
This unified approach was one of the major reasons YOLO became influential in computer vision.
Conclusion
YOLOv1 was a major milestone in the evolution of real-time object detection. By processing an entire image with a single neural network and directly predicting bounding boxes and class probabilities, it provided a simpler and faster alternative to many existing detection approaches.
Although YOLOv1 had limitations in localization accuracy and the detection of small or closely positioned objects, its unified architecture established the fundamental concept behind the YOLO family.
The progression from YOLOv1 to later versions demonstrates how object detection has continuously evolved toward better accuracy, efficiency, and flexibility while maintaining the goal of real-time performance.
Comments (0)
No comments yet. Be the first to share your thoughts!
Join the Conversation
Please log in to your Teltam account to post a comment on this article.
Log In to Comment